IT之家 · 智能时代 · 10/15/2026, 22:07:47
StepFun Open-Sources Step 5 Preview Weights with Day-0 Support from Huawei Ascend and Other Domestic Chips
StepFun has open-sourced the Step 5 Preview model weights, enabling deployment via vLLM, SGLang, and Transformers. Major domestic chipmakers including Huawei Ascend, MetaX, Biren, and Moore Threads announced Day-0 support, with Huawei leveraging its Atlas 950 SuperPoD to achieve high-efficiency inference optimization for trillion-parameter models.
SOURCE COVERAGEFull Original Report
Model weights are now available on Hugging Face and ModelScope. Developers can deploy OpenAI-compatible API services using vLLM or SGLang, or perform offline inference with Transformers.
Subsequently, Huawei, Biren Technology, MetaX, and Moore Threads officially announced Day-0 support.
According to Huawei, upon the open-source release of Step 5 Preview, Ascend achieved Day-0 support based on the vLLM inference engine, implementing efficient inference optimizations tailored to the model architecture and hardware characteristics.
On October 15, the first 1024-card Atlas 950 SuperPoD liquid-cooled supernode was activated in sync with the open-sourcing of Step 5 Preview, delivering performance comparable to advanced overseas computing power.
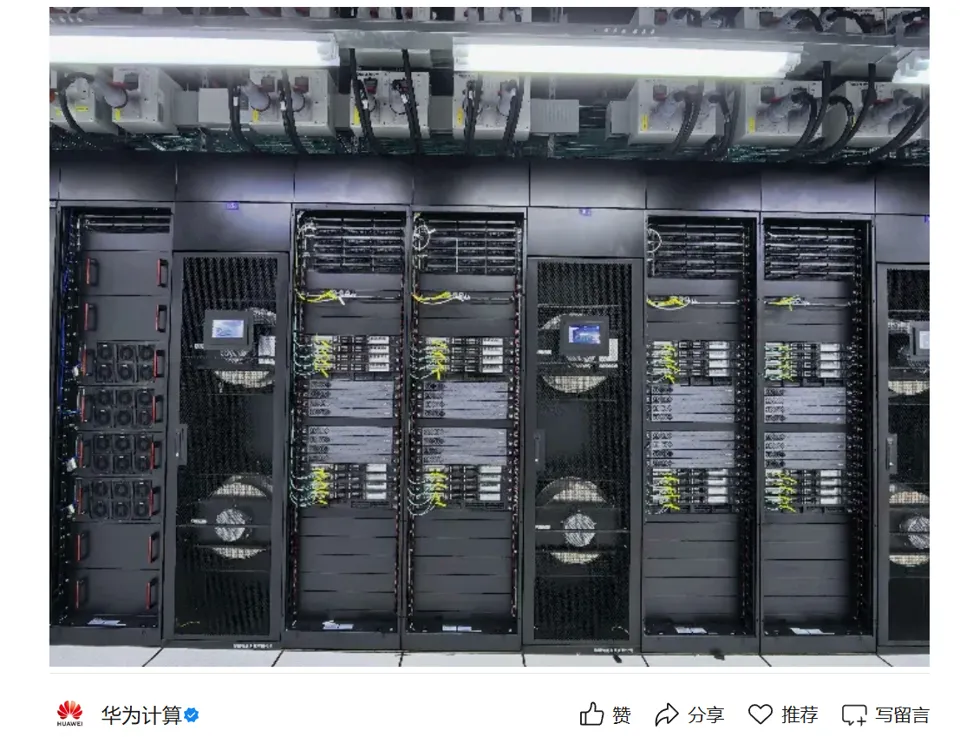
The Ascend Atlas 950 SuperPoD liquid-cooled supernode is built on the LingQu high-speed interconnect architecture and supernode technology system. As the industry's largest 1024-card supernode product, it provides massive computing power of 1 EFLOPS at FP8 precision and 2 EFLOPS at FP4 precision, efficiently meeting the inference requirements of trillion-parameter large models.
IT Home learned from Huawei that the Ascend 950 supernode features 256TB of globally unified memory addressing, TB-level inter-NPU bandwidth, and latency as low as 3μs, thoroughly breaking through communication bottlenecks for compute and storage resources within traditional clusters. Through systematic architectural innovation and unified scheduling of global resources, it achieves efficient release and stable operation of the entire cluster's computing power.
Huawei stated that Ascend, based on the vLLM Ascend inference engine, has co-developed an efficient inference optimization solution centered around the Step 5 Preview model architecture and the 950 supernode hardware characteristics. From fused operators combining Ascend C and Triton, to multi-stream parallelism and computation bubble optimization, to MTP speculative decoding and NPU Graph execution, the optimization pipeline between models, operators, and inference frameworks is continuously streamlined, providing efficient computing power support for Step 5 Preview deployment.
MetaX announced that its Xiyun C-series GPUs have completed deep Day-0 adaptation ahead of schedule. With a fully self-developed computing infrastructure, MetaX adds core support to the domestic Agent ecosystem, continuing to lead the race for rapid adaptation of domestic large models.
Since December 2025, MetaX has completed Day-0 adaptation for 43 mainstream flagship models. This covers leading model vendors such as Zhipu AI, Alibaba Qwen, MiniMax, DeepSeek, StepFun, and Tencent Hunyuan. The speed, quantity, and breadth of ecosystem coverage rank among the industry leaders.
On the hardware side, the Xiyun C-series GPUs are based on MetaX's proprietary XCORE architecture, featuring large-capacity, high-bandwidth memory and MetaXLink high-speed chip-to-chip interconnects. They offer mixed-precision computing power and linear scalability for clusters, naturally adapting to the compute and memory demands of MoE model expert scheduling and million-token long-context inference. These GPUs can stably handle single-machine multi-GPU setups and large-scale intelligent computing clusters.
On the software side, relying on MetaX's proprietary MXMACA full-stack software suite—which covers underlying drivers, the MXCC compiler, deeply optimized operator libraries, and adaptation layers for mainstream AI frameworks—the platform natively supports major AI development ecosystems. It compresses the traditional large model adaptation cycle from weeks to hours, significantly reducing model migration costs.
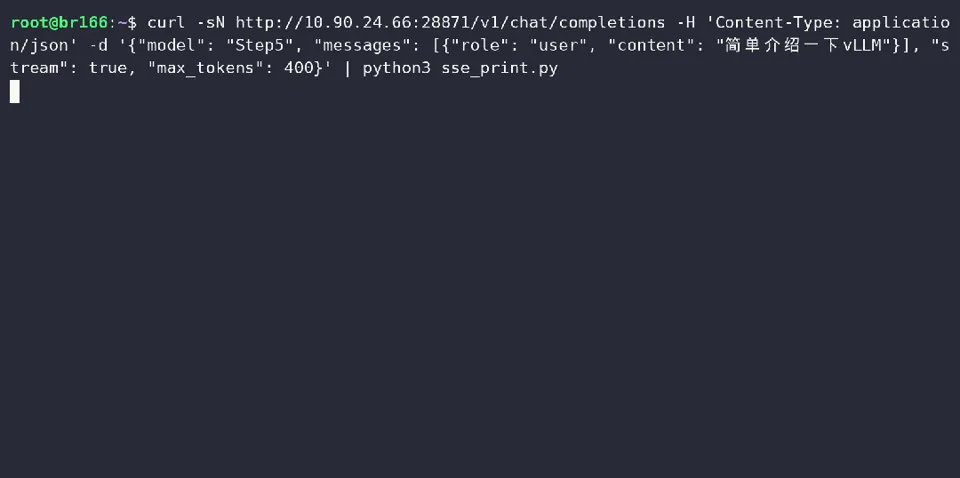
Biren Technology stated that during this Day-0 adaptation, focusing on Step 5 Preview's text understanding, generation, and efficient inference capabilities, Biren quickly completed model adaptation on its Bili series general-purpose GPUs using the vLLM AI inference framework and the mature BIRENSUPA software stack. Key pipelines including weight loading, service startup, and text generation were established, followed by functional and accuracy verification.
Additionally, Biren's proprietary full-stack multi-agent platform SUPACODE automatically parses and adapts critical modules of Step 5 Preview, such as DSA, SummaryCache, and MoE, rapidly establishing the full inference pipeline on this basis.
Moore Threads announced that its flagship AI training and inference integrated smart computing card, the MTT S5000, along with the MUSA software stack, has completed Day-0 ultra-fast adaptation and efficient execution for the model. Addressing the core capability characteristics of Step 5 Preview, the MTT S5000 underwent precise end-to-end adaptation and tuning across hardware computing power, the software stack, and the inference framework.