The Decoder · 10/13/2026, 19:06:46
Anthropic Deploys Anti-Distillation Defenses: Classifier-Based Interception Cuts Claude Reasoning Token Theft by 90-99%
Anthropic unveiled new defenses against industrial-scale model distillation attacks, reducing the extraction of Claude's internal Chain-of-Thought (CoT) reasoning tokens by 90-99%. The system employs a specialized classifier to detect and automatically ban accounts involved in systematic data siphoning via hundreds of thousands of fake profiles. While acknowledging false positives affecting legitimate users, this move highlights a significant upgrade in protecting core reasoning capabilities from being replicated by competitors.
SOURCE COVERAGEFull Original Report
Anthropic is battling large-scale distillation attacks on its Claude models. In these attacks, companies systematically copy an AI model's capabilities to train their own, smaller models. Anthropic says its new defenses have cut the volume of extracted reasoning tokens, the model's internal chain-of-thought steps, by 90 to 99 percent. Attackers use networks of hundreds of thousands of fake accounts to pull it off.
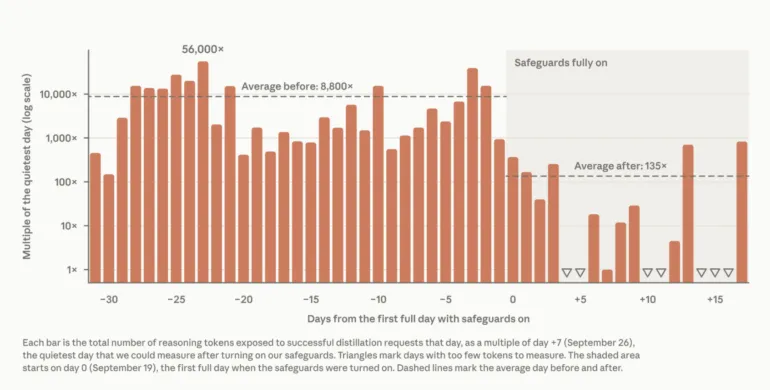
According to Anthropic, successful extraction attempts dropped sharply | Image: Anthropic
Anthropic names Chinese companies Zhipu and Moonshot as participants. Zhipu allegedly siphoned cyber capabilities from leading US models for its GLM-5.3 model, while Moonshot secretly routed queries through Claude. The stolen capabilities could end up in foreign military and surveillance systems.
Anthropic now restricts access to Claude's internal reasoning steps, runs a classifier that detects extraction attempts, and automatically bans flagged accounts. Tens of thousands have already been banned. Anthropic is calling on other AI developers to adopt similar protections, although the company admits that legitimate users are getting caught up in the process too.